Paper summary
Preserve each expert’s output
Compressing an expert model around the outputs it produces can save memory while retaining more of its accuracy.
Mixture-of-experts models activate only a few experts per token, yet their stored parameters still consume substantial GPU memory. Residual sparsification reduces that footprint by sharing a base matrix and compressing each expert’s remaining differences. The paper shows why minimizing errors in those matrices separately can still distort the expert’s final output: the projections interact through nonlinear hidden representations.
Score what a removed dimension changes
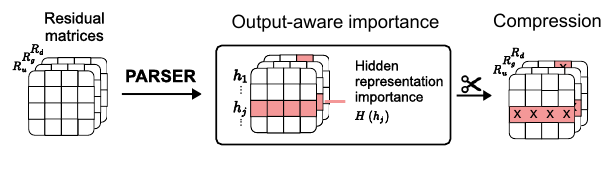
PARSER estimates output importance: how much an expert’s output changes when a hidden dimension loses its expert-specific residual contribution. It uses a calibration dataset to estimate this effect, accounting for the coupled up, gate and down projections.
A dimension’s contribution to the output guides its retention.
Scores are pooled across experts within each MoE layer. PARSER removes the lowest-scoring dimensions up to the compression budget, allowing more important experts to retain more dimensions. It removes the corresponding residual rows and columns together while keeping the shared base.
 View full-size figure
Accuracy at a comparable memory footprint
The main evaluation runs Qwen1.5-MoE-A2.7B and DeepSeek-V2-Lite on one NVIDIA B200 GPU. It averages zero-shot accuracy across seven tasks, using bfloat16 and batch size 64. The reported setting compresses 90% of residual dimensions within the last two-thirds of layers.
Against D2MoE, the strongest accuracy baseline in this comparison, PARSER narrows the gap to the uncompressed model by 1.41× on Qwen and 1.44× on DeepSeek. Its average per-task peak GPU memory is 24.26 GB and 28.97 GB respectively, comparable to the compressed baselines.
| Model | Uncompressed | D2MoE | PARSER |
|---|---|---|---|
| Qwen1.5-MoE-A2.7B | 59.12 | 45.22 | 49.24 |
| DeepSeek-V2-Lite | 59.64 | 41.66 | 47.16 |
Key takeaways
- Compression error matters through the expert’s output. Matrix-by-matrix objectives miss interactions between projections that output importance captures.
- Experts need not lose equal proportions of their dimensions. Pooling importance scores within a layer lets the compression budget follow their relative contribution.
- The comparison preserves more accuracy at similar memory use. PARSER outperforms D2MoE on the reported seven-task averages for both evaluated models.