Paper summary
Change parallelism as training progresses
Training strategy affects both iteration speed and progress toward the desired model quality.
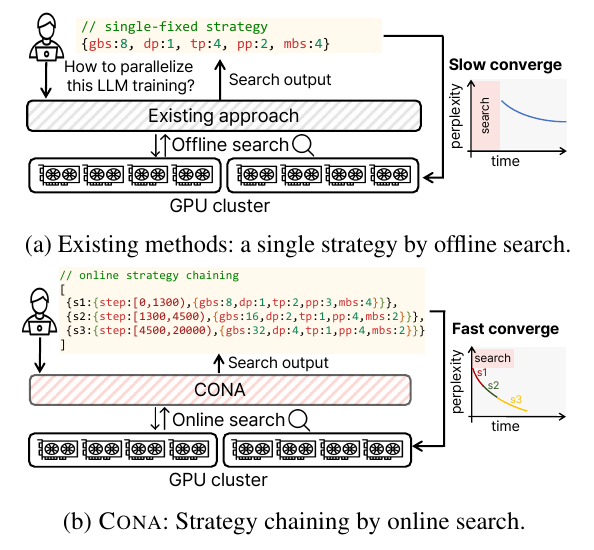
A parallelism strategy sets how data, tensors and pipeline stages are distributed, together with micro- and global-batch sizes. The paper finds that the strategy giving the fastest progress in validation perplexity changes during training. Selecting one fixed strategy for short iterations therefore misses opportunities to reach the target quality sooner.
Search while training, then switch
CONA tracks a surrogate for training-loss reduction per second using compute throughput and gradient-noise statistics. It searches in the background for a strategy at the next larger global-batch size and switches through lightweight checkpointing when that candidate’s surrogate score exceeds the current strategy’s.
The decision follows learning progress per second.
Bayesian optimization estimates candidate iteration times without GPU profiling. The search overlaps training; a new search begins after a switch advances the batch-size frontier.
 View full-size figure
Time to a fixed quality target
The evaluation trains GPT-3 1.3B, Llama-3.2-1B and BERT-Large on WikiText-103 using 16 A6000 GPUs across two nodes connected by 100 GbE. For the target validation perplexity of 30, CONA takes 2.4, 1.8 and 1.6 hours respectively.
Across these models and five baselines—AMP, Alpa, Metis, Galvatron and vTrain—the reported time-to-target improvements range from 1.4× to 9.6×. These are single-run end-to-end results for that target. The paper separately evaluates final perplexity under 10,000 iterations and elapsed time under a fixed token budget, keeping those measurements distinct.
| Model | Time |
|---|---|
| GPT-3 1.3B | 2.4 h |
| Llama-3.2-1B | 1.8 h |
| BERT-Large | 1.6 h |
Key takeaways
- Convergence depends on both iteration speed and learning progress. Strategy selection targets time to the desired validation quality.
- The preferred strategy can change during training. Throughput and gradient statistics support online changes to parallelism and batch size, with search running alongside GPU work.