Paper summary
Reduce two different kinds of GPU waiting
Unequal GPUs can train together more efficiently when each receives suitable work and exchanges smaller updates.
Synchronous training across regions makes faster GPUs wait for slower workers, then makes all workers wait for updates to cross the wide-area network. GeoMesh treats these as separate problems. It retains synchronized updates while changing both how work is assigned and how updates are communicated.
Balance local work and compress shared updates
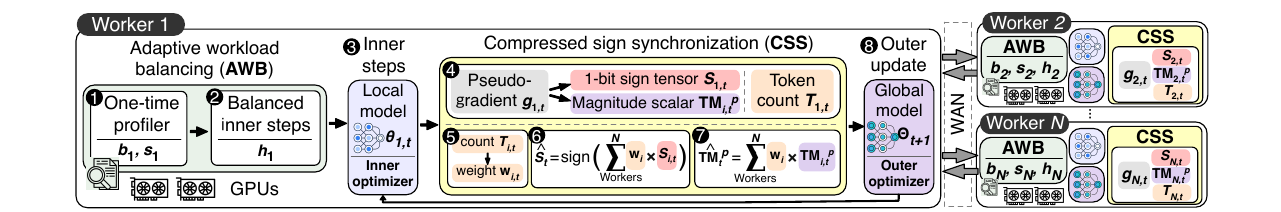
A one-time profiler estimates each worker’s feasible batch size and training speed. GeoMesh assigns batch sizes and inner-step counts to bring workers’ local training times closer together according to each GPU’s measured capability.
Faster GPUs receive more local work to balance the time spent before synchronization.
Workers exchange bit-packed pseudo-gradient signs with magnitude and token-count metadata. Token-weighted aggregation accounts for their unequal workloads, while the magnitude information restores the update scale lost by sign compression.
 View full-size figure
Training with heterogeneous GPUs and an emulated WAN
The main evaluation uses H100, A100, L40S and RTX 6000 Ada workers, with WAN rates emulated from Azure inter-region measurements. The authors train 150M, 300M and 500M LLaMA-style models on C4.
For the 150M model, GeoMesh reaches perplexity 30 in 1.1 hours: 70.2% less time than DiLoCo and 43.8% less than HALoS. For 300M and 500M, it reaches the respective perplexity targets of 25 and 20 in 2.6 and 7.5 hours, versus HALoS’s 7.9 and 22.8 hours. DiLoCo does not reach those two targets within the stated 30- and 50-hour budgets. These main results are reported from one run per configuration.
| Model / target | GeoMesh | HALoS |
|---|---|---|
| 300M / 25 | 2.6 h | 7.9 h |
| 500M / 20 | 7.5 h | 22.8 h |
Key takeaways
- Geographic training has two distinct waiting costs. Unequal worker speeds and WAN synchronization require workload balancing and communication reduction together.
- Unequal work must remain visible after compression. Token counts and magnitude metadata carry information needed to combine the updates.
- The measured benefit reaches training quality sooner. On the 150M model, GeoMesh reaches perplexity 30 ahead of both synchronous and asynchronous baselines.