Paper summary
Find the right collections before retrieving documents
Independent document collections can answer a query together without retraining a router whenever a new collection joins.
Federated RAG retrieves evidence from independently managed document collections. Sending every query to every collection increases communication, while trained routers require updates as collections change. RAGSpot separates the routing decision from local retrieval so each collection can keep its own retrieval model.
Route through a shared collection map
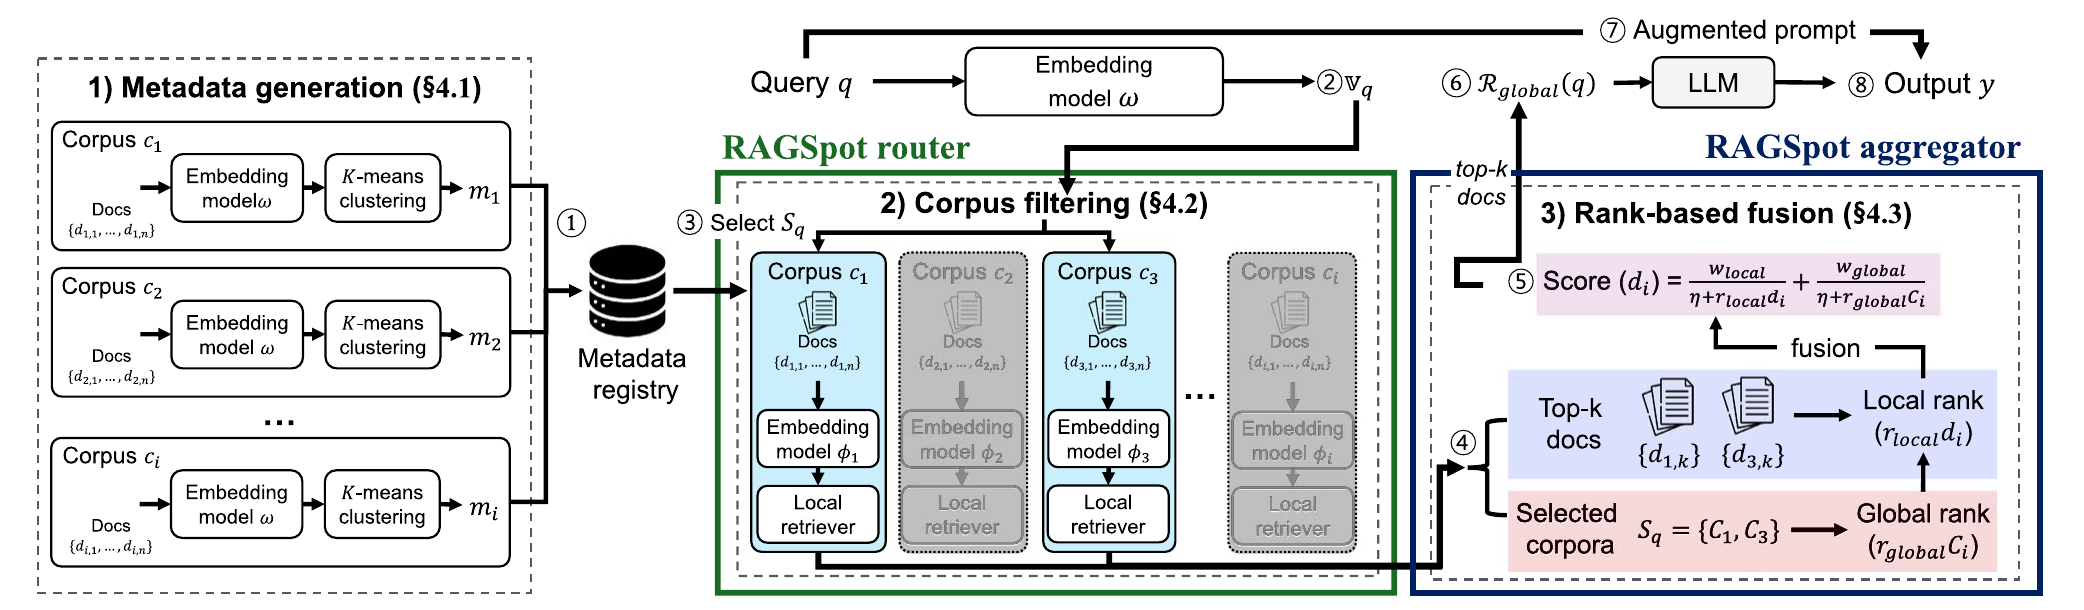
Each collection uses a common routing encoder to group document vectors into clusters, then publishes their centers and radii. For a new query, the router compares its distance to nearby cluster centers relative to each cluster’s radius. This selects collections without requiring their local retrieval encoders to match.
The shared representation decides where to look; each collection decides how to search its own documents.
Selected collections return their top documents. RAGSpot combines each document’s local rank with its collection’s relevance rank. A new collection joins by registering its routing metadata, without retraining the router.
 View full-size figure
What the retrieval experiments show
The authors test six BEIR collections using 3,726 single-corpus queries and 3,464 synthetic two-corpus queries formed by concatenation. The table compares RAGSpot with the trained RAGRoute baseline. nDCG measures ranking quality; Recall measures coverage of relevant documents. Both are reported at ten retrieved results.
RAGSpot improves both ranking and coverage in these comparisons without router training. The composite workload uses concatenated queries to test routing to two known sources.
| Workload / method | nDCG@10 | Recall@10 |
|---|---|---|
| Single / RAGRoute | 0.28 | 0.39 |
| Single / RAGSpot | 0.35 | 0.51 |
| Composite / RAGRoute | 0.11 | 0.10 |
| Composite / RAGSpot | 0.16 | 0.16 |
Key takeaways
- Federated routing need not standardize local retrievers. Shared cluster metadata provides a common routing view while collections retain their own retrieval models.
- Source selection and evidence ranking operate at different levels. Combining corpus and document ranks connects collection relevance to individual results.
- A new collection can join through metadata. This avoids retraining a supervised router whenever the federation changes.